How to Translate a Book-Length Manuscript: A Complete Workflow
Translating 300 pages is not translating one page 300 times. The work that determines whether the result is usable happens before you translate anything and after the machine has finished. Here is the whole process, in the order that stops you from redoing it.
This applies to a novel, a doctoral thesis, a technical handbook, a company history, a set of case files — anything long enough that you cannot hold it all in your head. The tool you use matters less than the sequence, so the workflow below is written to work with whatever you have. Where a specific step is much easier with software built for long text, it is called out.
Before you start: decide what "done" means
A translation for comprehension — you need to know what the document says — is a different job from a translation for publication, where the result carries your name. The first is largely mechanical and can be finished in a day. The second requires a native reviewer and is not something any tool completes on its own. Decide which one you are doing now, because it changes how much of stages 6 and 7 you need.
Stage 1 — Clean the source text
Every hour here saves several later. Machine translation is unusually sensitive to formatting damage, and the damage is easy to miss because the output still reads fluently.
Get the manuscript into plain, continuous text and fix the following:
- Hard line breaks inside sentences. The biggest one. PDFs and old word-processor files often break every line at a fixed width, so a single sentence arrives as four fragments. Each fragment gets translated as though it were a complete thought. Join them into continuous paragraphs.
- Hyphenation across line ends. "trans-" and "lation" on separate lines become two words that mean nothing. Search for a hyphen followed by a line break and close them up.
- Page furniture. Headers, footers, page numbers and running titles interleaved into the text will be translated as if they were sentences, appearing mid-paragraph in the output. Strip them.
- Footnote markers and footnote text. Decide now: pull footnotes out into a separate document and translate them as their own job, or leave them inline and accept that they will interrupt sentences. Separating them is almost always better.
- Tables and figure captions. Extract them. A table flattened into a paragraph translates into unusable prose.
Keep the cleaned source as its own file and do not overwrite it. You will come back to it, and you want the version you actually translated, not the original.
Stage 2 — Build the term list
This is the stage people skip and the one that most reliably separates a good result from a mediocre one. It takes under an hour for a full manuscript.
Make a two-column list. Left column: the source term. Right column: the exact translation you want, every time. Include:
- Every person's name, especially when the languages use different scripts.
- Every place name, particularly those with both a local and an international form.
- Organisations, products, titles — anything capitalised.
- Terms of art in your field. If the document is a thesis, this is your existing vocabulary. If it is a novel, it is the invented words, the recurring epithets, and the names of things that only exist in that book.
- Recurring phrases and motifs. A refrain that appears twelve times should appear identically twelve times, and by default it will not.
Two decisions to make while you are here, and to write at the top of the list: formality (does the whole document use formal or informal address?) and whether names are transliterated or left in the original script. Both are consistency traps, and both are cheap to decide now and expensive to fix across 300 pages later.
Stage 3 — Translate one chapter as a test
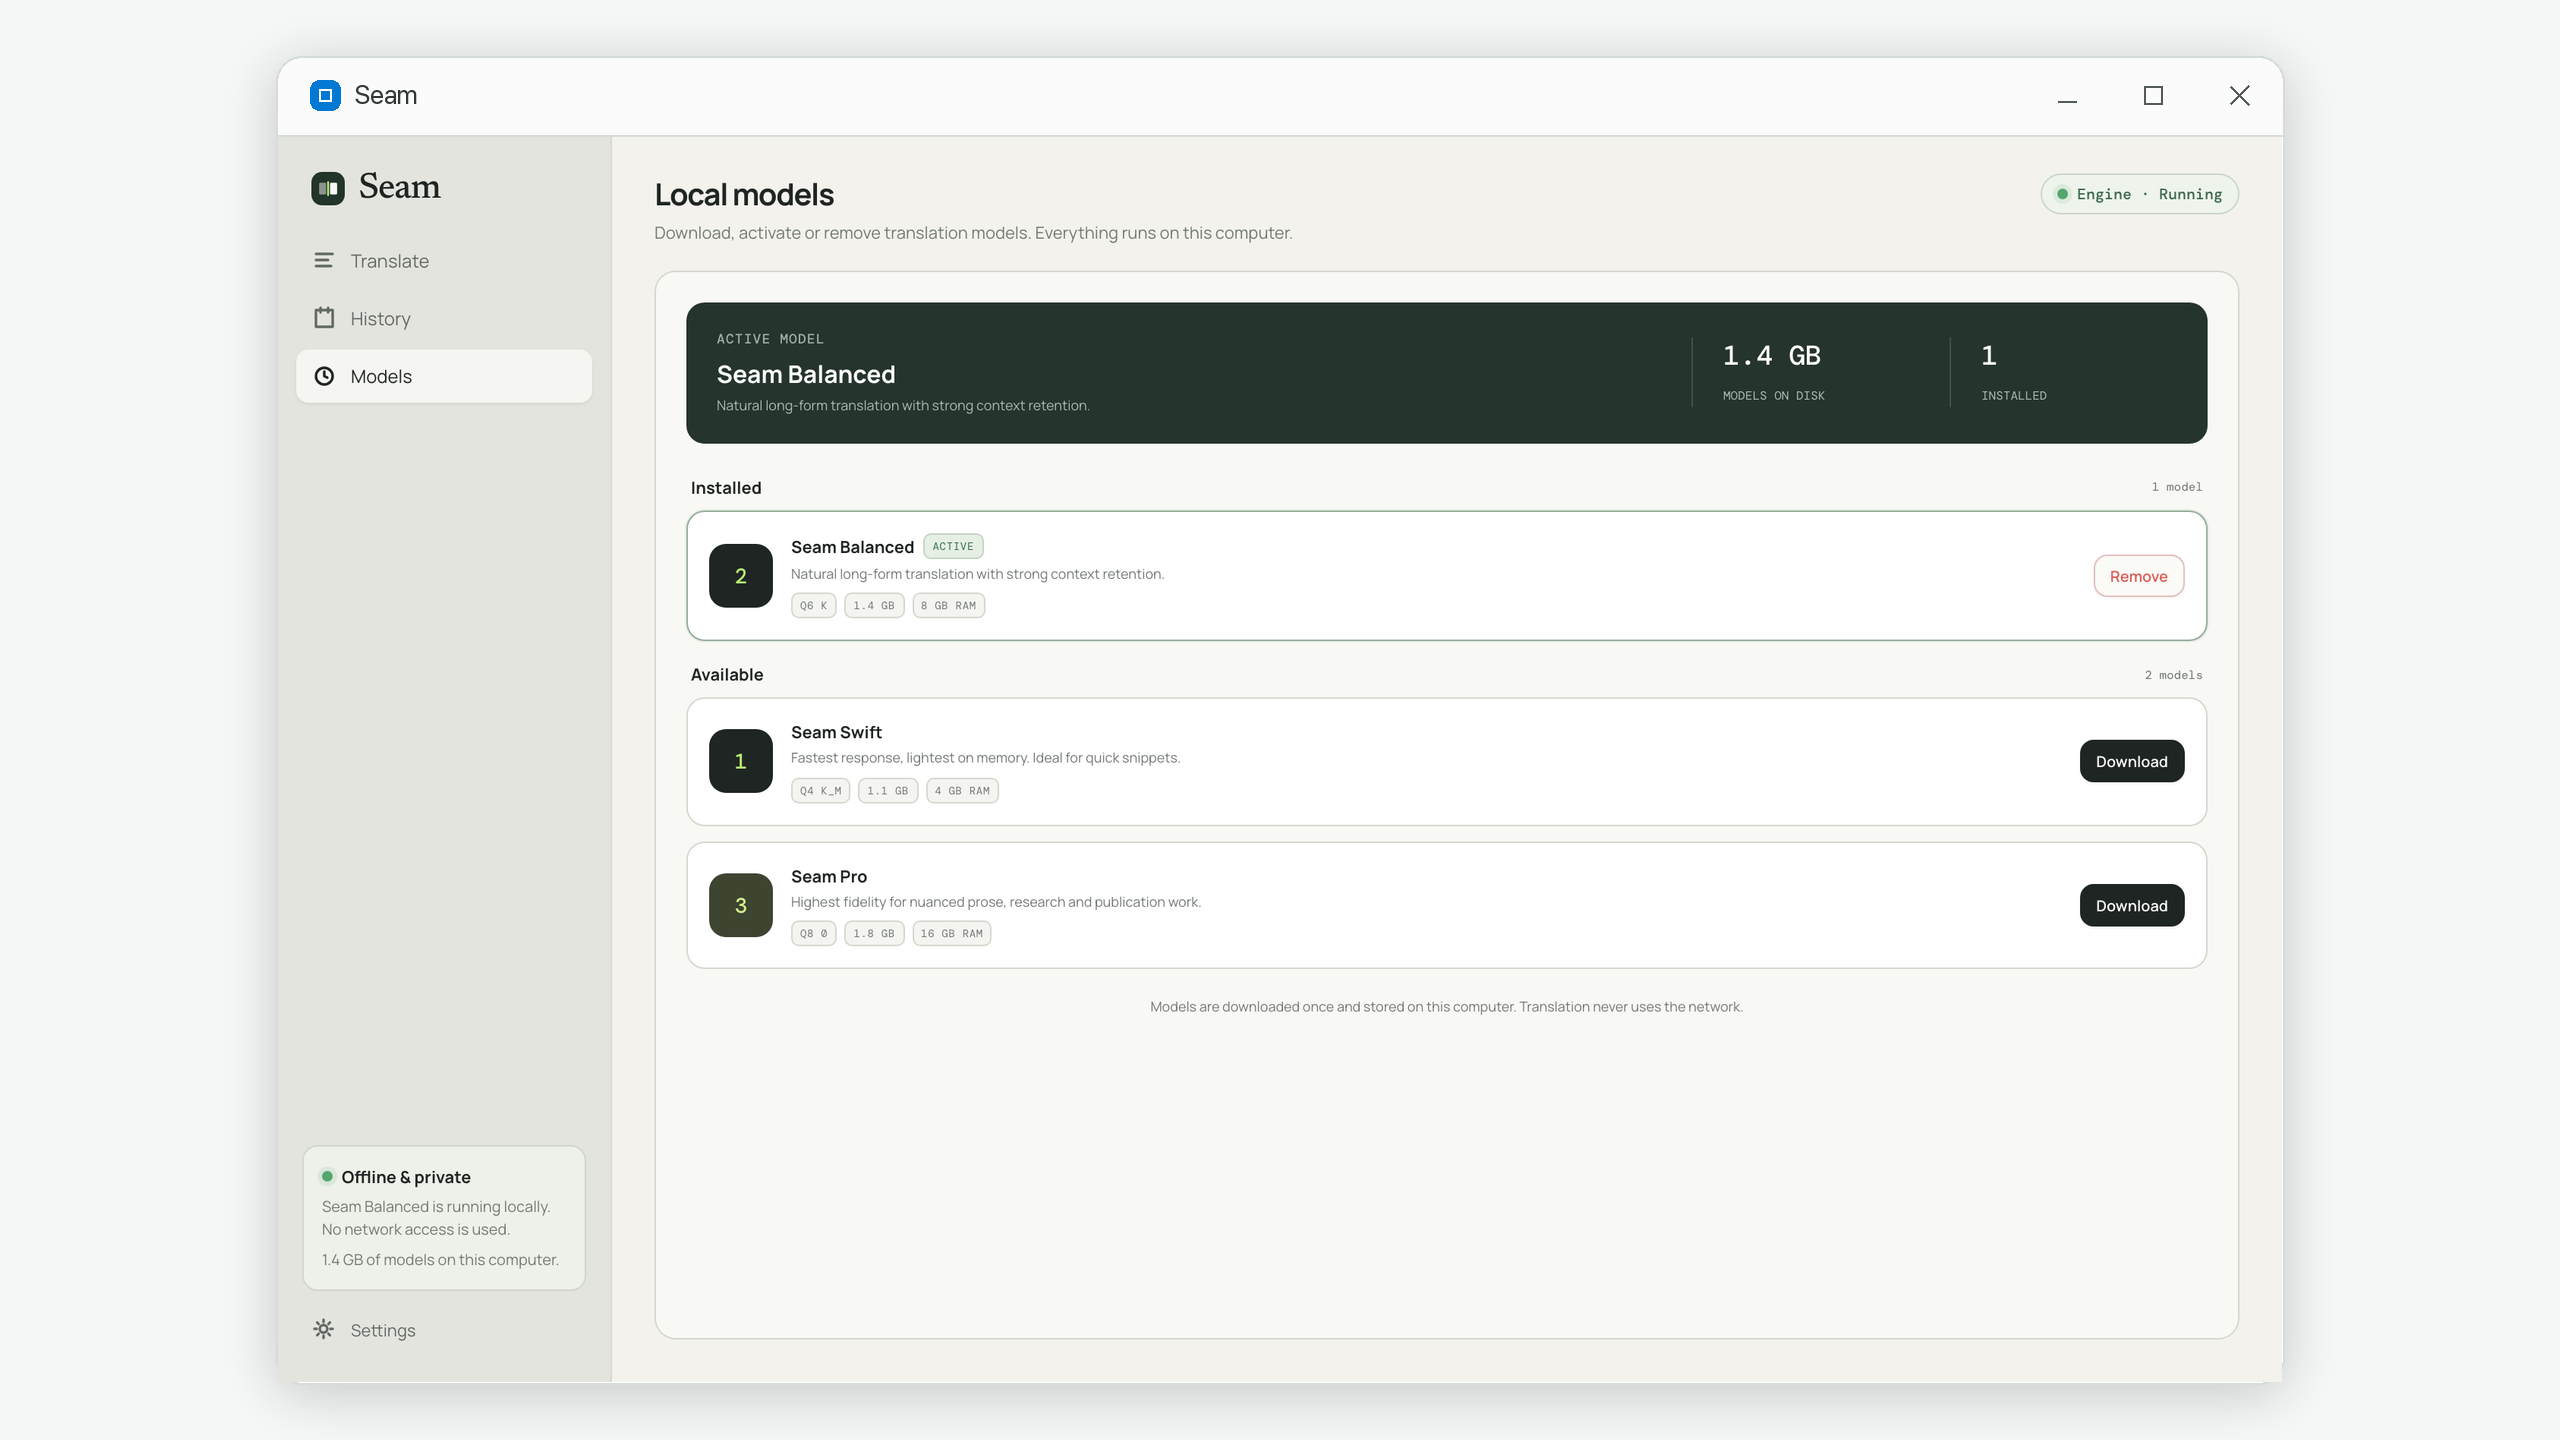
Do not start the full run. Pick one representative chapter — not the first one, which is usually atypical — and translate only that.
This is a 30-minute investment that answers four questions:
- Is the quality good enough for your purpose at all? Better to learn this now than after eleven hours of processing.
- Which model should you use? Run the same chapter through a faster model and a higher-fidelity one and compare directly. The difference is often smaller than expected on informational text and larger than expected on dialogue and nuanced prose.
- How long will the whole thing take? Time the chapter, divide by its character count, multiply by the manuscript's. Now you know whether this is a lunch break or an overnight job.
- What did your term list miss? You will always find terms you did not think of. Add them before the main run.
Stage 4 — Run the full manuscript
With the test done, this stage should be boring, and boring is the goal. Two things determine whether it is.
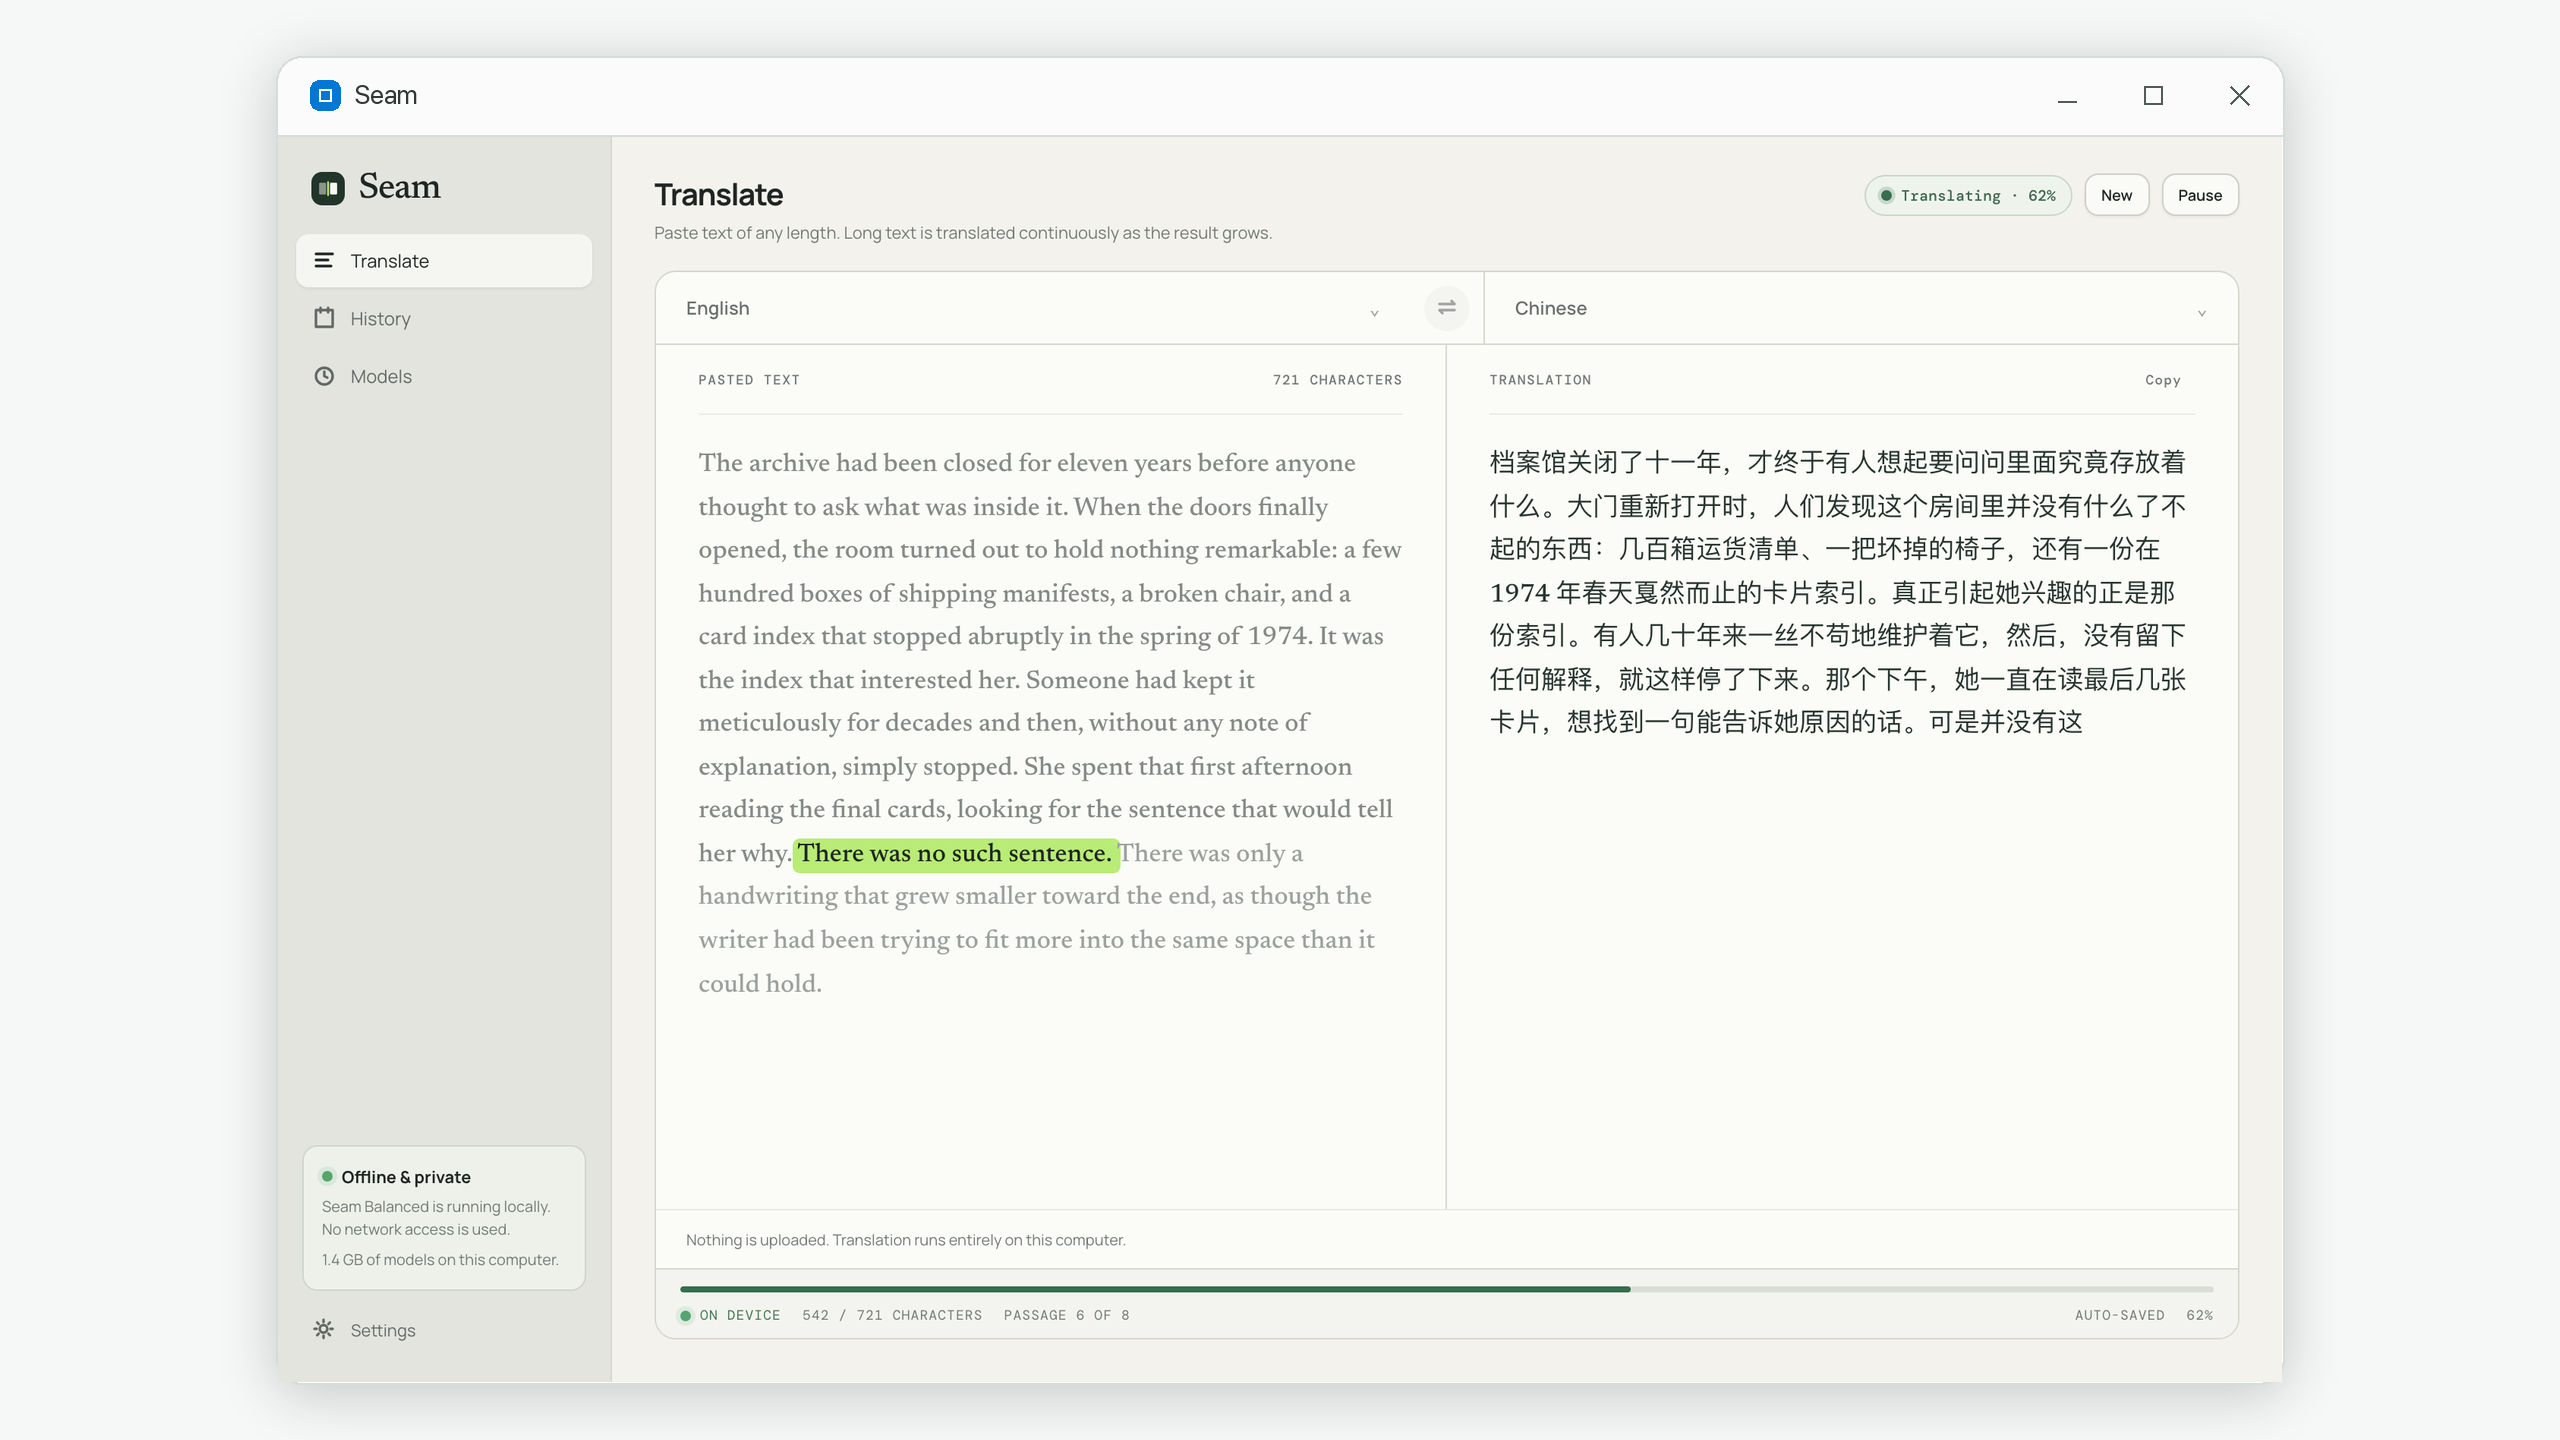
Split at meaningful boundaries. A long document must be broken into pieces to be translated at all — no model can hold a book at once. If you are doing this by hand, cut at chapter or section breaks, never mid-sentence and never at a fixed character count. If your tool does the splitting, it should be cutting at sentence endings and line breaks rather than counting characters. This one detail affects the output quality more than most people expect, because a fragment handed to a model without a complete thought in it translates badly at both ends of the cut.
Make sure an interruption is survivable. A manuscript-length run takes hours. Laptops sleep, machines restart, and you will want to close the program at some point. Before starting a long job, confirm what happens if it stops halfway — whether it resumes, or whether you lose everything and start again. If it does not resume, run it in pieces you can afford to lose.
A practical note: run this on a machine you are not otherwise hammering. Local translation is processor-intensive, and doing it in the background while you edit video will slow both jobs down.
Stage 5 — Reassemble and restore the formatting
You now have a translation. It is plain text and it has lost the structure you stripped in stage 1. Put it back before you review, not after — reviewing unformatted text is much harder and you will read past errors.
- Check the paragraph count matches the cleaned source. A mismatch means a passage was dropped or duplicated, which is the single most damaging silent error in this whole process.
- Restore headings and hierarchy.
- Reinsert footnotes, tables and captions from their separate jobs.
- Verify numbers, dates and units survived. Spot-check twenty of them against the source. Digits get mangled more often than words do, and no reader will catch it for you.
Stage 6 — The consistency pass
Now bring back the term list. This pass is mechanical, fast, and catches the errors that most damage a reader's confidence.
For each entry in your list, search the whole translation and confirm exactly one rendering is used. Where there are several, replace them all with your chosen one. Do this term by term across the entire document rather than section by section — it is faster and it does not miss anything.
Then, in order:
- Check formality markers for a mix of registers, and normalise.
- Read one paragraph either side of every chapter and section boundary. Errors cluster at joins.
- If translating out of a gender-neutral language, check each character's pronouns are consistent.
- Search for source-language characters left untranslated — a quick way to find passages that were skipped.
- Read the first and last pages properly. They carry disproportionate weight.
Stage 7 — Decide what gets a human
If this translation is for comprehension, you are done. If it is going to be published, it is not, and no amount of tooling changes that.
The useful insight is that you rarely need a human for all of it. You now have a complete draft, which means you can direct professional time precisely instead of commissioning a cover-to-cover translation. Prioritise, in this order:
- Anything with legal or safety consequences. Contract clauses, dosages, warnings, technical specifications, financial figures.
- The opening and closing. Where readers form and keep their judgement.
- Dialogue and anything voice-driven. The hardest thing for a machine to sustain, and the most obvious when wrong.
- Marketing and promotional copy. Persuasion translates worse than information does, almost universally.
A reviewer working from a complete draft is doing a fundamentally cheaper job than one translating from scratch — and if you hand them your term list alongside it, cheaper again.
A rough time budget for a 300-page manuscript
| Stage | Typical time | Can it be skipped? |
|---|---|---|
| 1 · Clean the source | 2–4 hours | No. Damage here propagates everywhere. |
| 2 · Term list | 1 hour | Technically yes; costs far more in stage 6. |
| 3 · Test chapter | 30 minutes | No. This is your insurance. |
| 4 · Full run | Hours, unattended | — |
| 5 · Reassemble | 1–3 hours | No. |
| 6 · Consistency pass | 2–4 hours | Only for a throwaway draft. |
| 7 · Human review | Varies | Yes for comprehension; no for publication. |
Roughly a day and a half of your attention, plus unattended processing time. That is the realistic figure, and it is worth knowing before you promise a deadline.
Where Seam fits
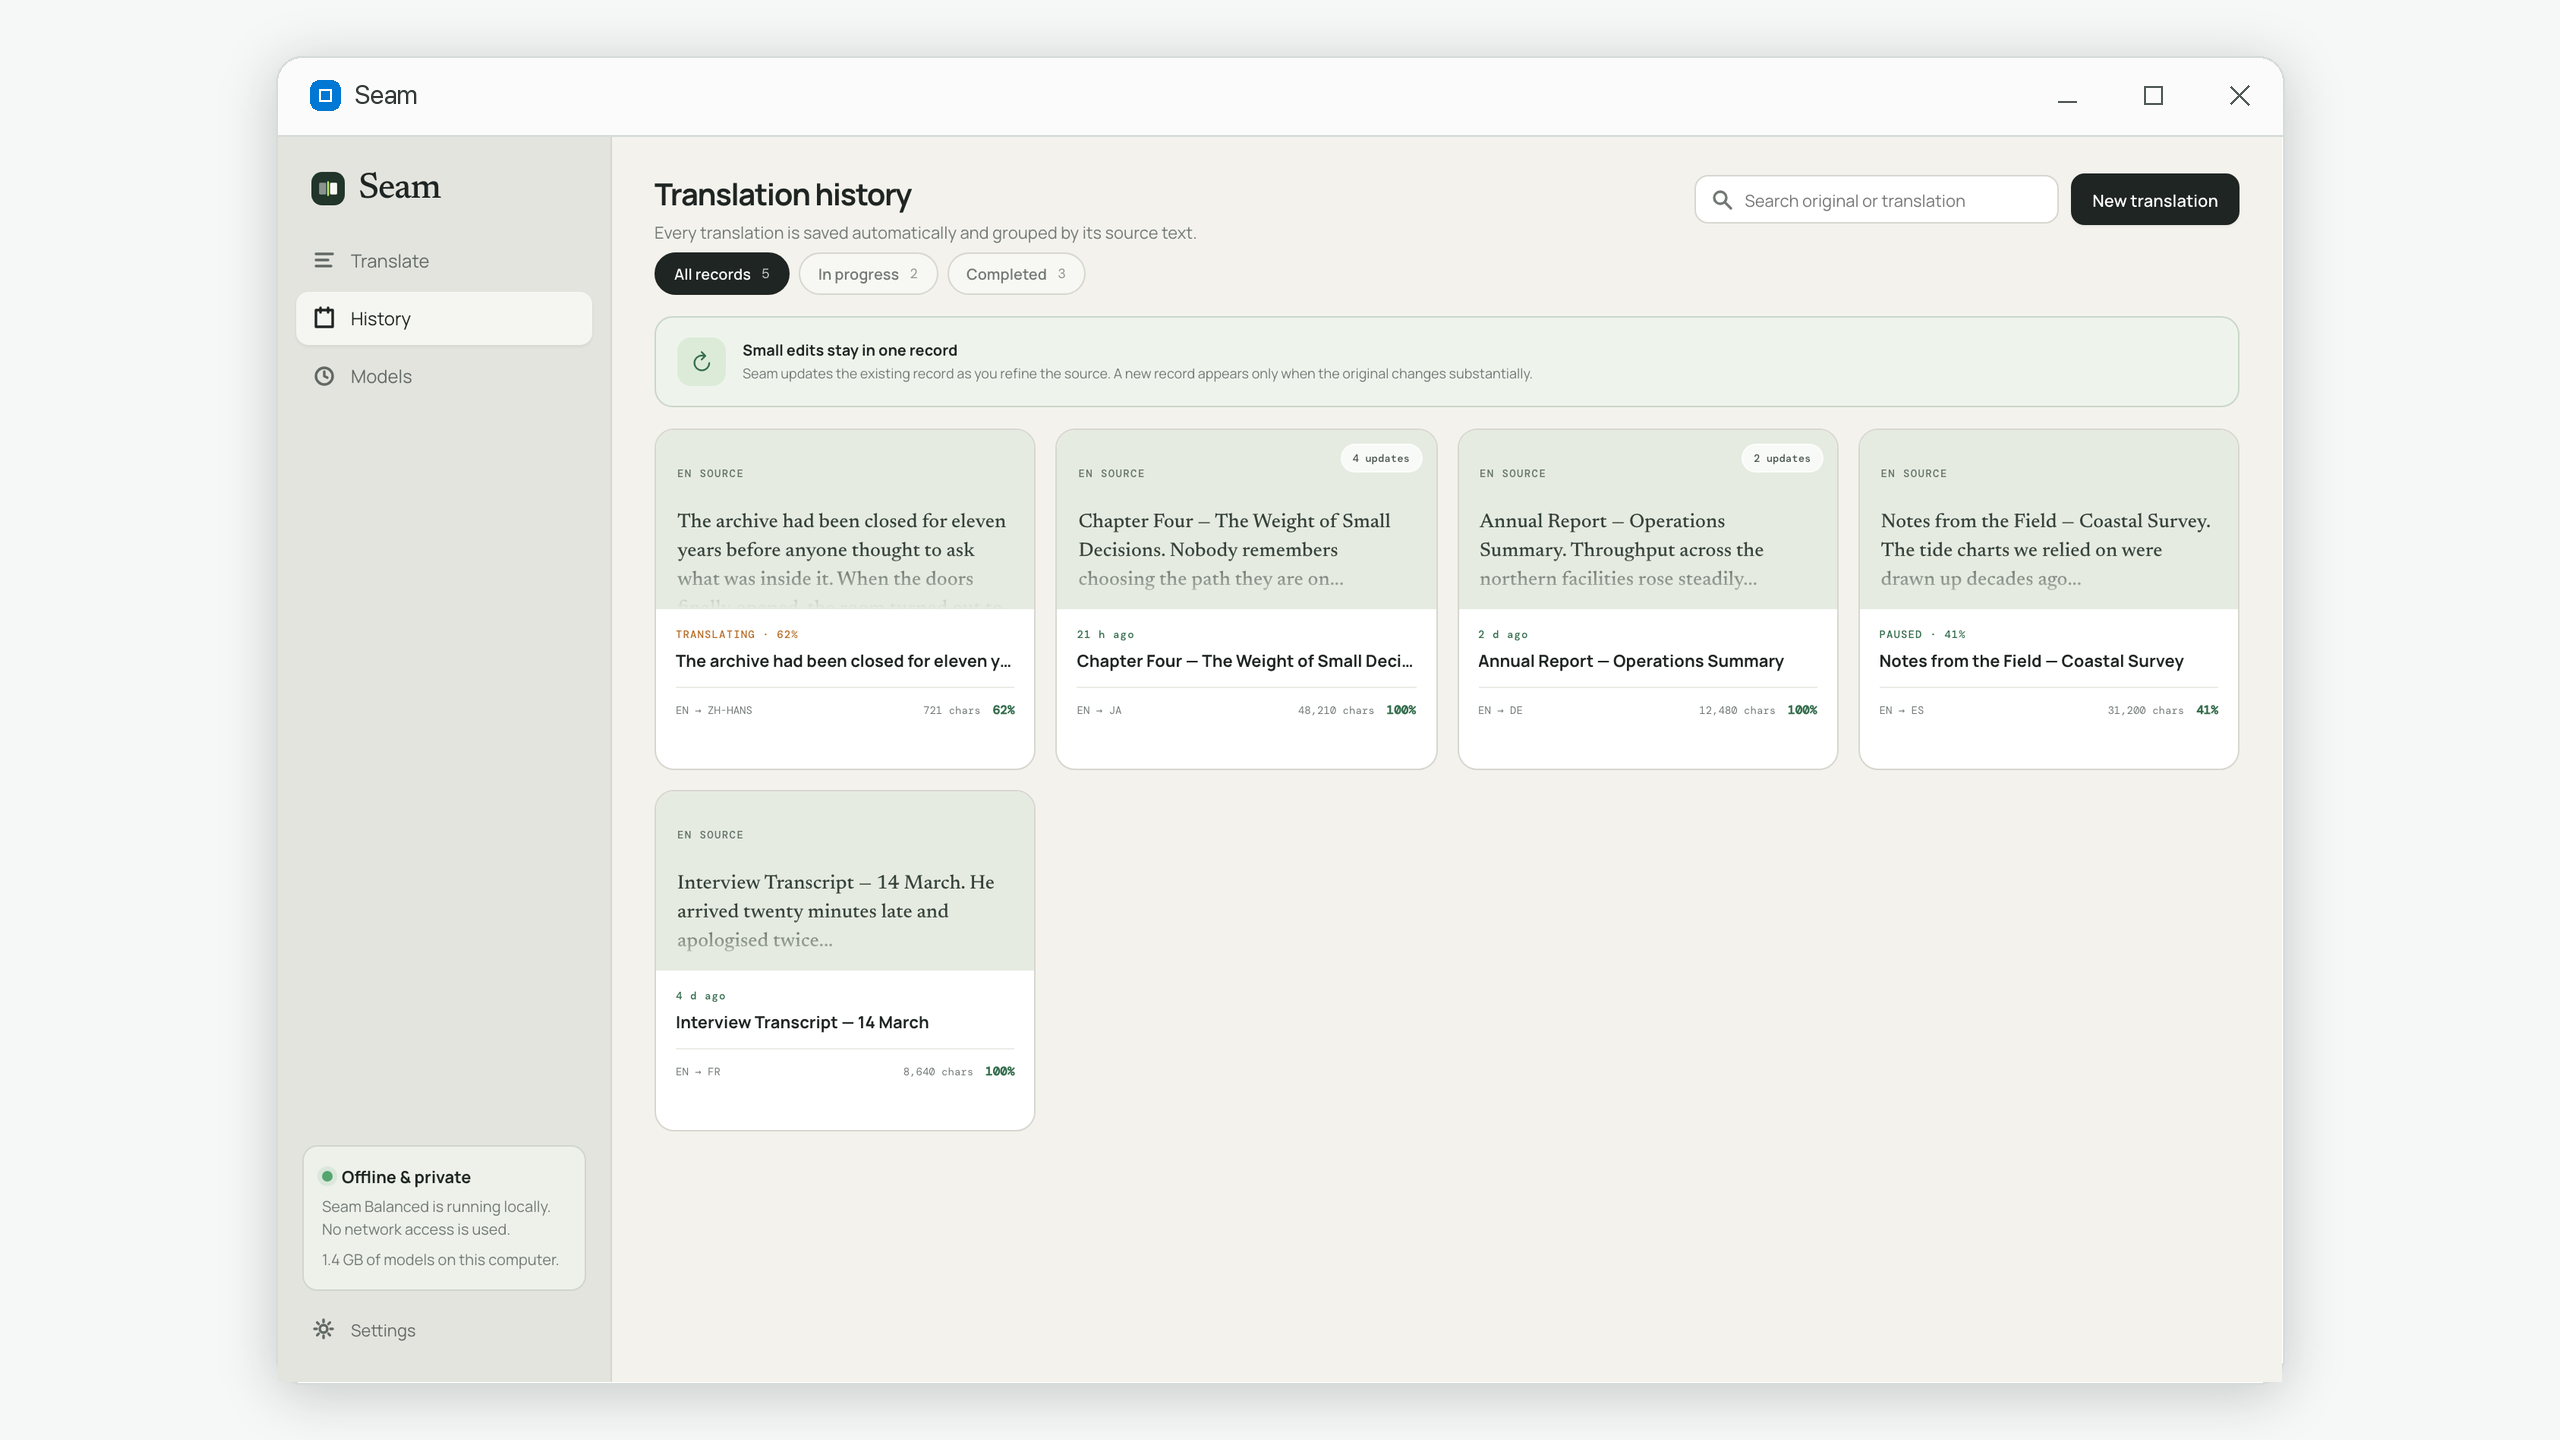
Seam is a desktop translator built specifically for stage 4, which is the stage most tools handle worst. It exists because the alternative — cutting a manuscript into chunks by hand, pasting them one at a time into a browser, and stitching results back together — is slow and quietly lossy.
You paste the entire manuscript. Three things then matter for this workflow:
- The splitting is done for you, at real boundaries. Cuts land on sentence endings and line breaks near a target size rather than at a fixed character count, and the pieces are rejoined exactly as they were cut — no whitespace quietly lost between passages.
- An interrupted run resumes. Each passage is saved as it finishes, so closing the app, restarting the machine, or pausing overnight costs you the current passage, not the job.
- Nothing is uploaded. For an unpublished manuscript or a thesis under embargo this is often the deciding factor: the text never leaves the computer, so there is no third party in the chain and nothing to disclose.
Stages 1, 2, 6 and 7 remain your work with any tool. That is not a limitation to engineer away — it is where a translation actually becomes good.
Common questions
How long does a 300-page manuscript take to translate?
On an ordinary desktop computer running a local model, expect several hours of unattended processing. It is an overnight job rather than a coffee-break one, which is why resuming after an interruption matters more than raw speed.
Should I translate chapter by chapter or all at once?
All at once, if your tool splits properly and can resume — fewer manual handoffs means fewer dropped or duplicated sections. Chapter by chapter only if you are working by hand or your tool cannot survive an interruption.
Can I keep editing the source while translating?
Finish the run first. Editing the source mid-job means the translation no longer corresponds to any single version of the manuscript, and reconciling that later is worse than waiting.
What if my manuscript is a scanned PDF?
You need OCR before any of this. Budget real time for stage 1 — OCR output typically has hard line breaks, hyphenation and page furniture all at once, which is exactly the combination that damages translation quality most.
Is machine translation good enough to publish?
Not without a native-speaker review, in any language pair, from any tool. What it is good enough for is producing a complete draft that makes the human review dramatically cheaper and faster than translating from nothing.
Seam translates manuscripts of any length on your own computer, resumes after interruptions, and never uploads the text. Get it on the Microsoft Store.